Make talent quality your leading analytic with skills-based hiring solution.
Most coding tests for hiring fail because they measure how well a candidate memorized algorithm puzzles, not how well they build software. They also run too long and in unfamiliar environments. Tests that work use real tasks, take 45 to 60 minutes, allow normal resources and look like the job. Coding Simulations are built around that idea.
Technical hiring still needs coding tests. Resumes alone are unreliable, and interviews favor confident talkers. The problem is not testing. It is what most tests choose to measure.
Done well, coding tests give hiring teams three things interviews cannot:
Skill tests do not answer every question. David Galownia, CEO of Slingshot, made the point that a candidate can ace an assessment and still not fit the team. Testing narrows the field. Interviews and team conversations still decide the hire.
Algorithm puzzles reward candidates who practiced on puzzle sites. Many strong engineers spend their days designing APIs, debugging production issues and reading other people’s code. A test that asks for an obscure sorting algorithm under a timer screens out people who would do the job well.
Multi hour take home projects ask candidates to work unpaid, often on a weekend. Experienced engineers with options skip them. Completion rates drop, and the people who finish are not always the people you most wanted.
Coding in a bare text box, with no autocomplete, no documentation and no way to run tests, is not how anyone works. Candidates who would perform well in a normal setup look worse than they are.
Engineers use documentation, search and increasingly AI coding assistants. A test that bans every resource measures something other than the job. A test that allows everything without tracking how it was used measures nothing.
| Weak coding test | Strong coding test |
|---|---|
| Algorithm puzzle unrelated to the role | Task drawn from the actual job |
| Two to eight hours | 45 to 60 minutes |
| Bare editor, no resources | Familiar IDE, documentation allowed |
| Scored only on pass or fail | Scored on correctness, code quality and approach |
| Same test for every role | Matched to frontend, backend, data, QA or DevOps work |
| No integrity controls | Proctoring and plagiarism checks |
A checklist for your next coding assessment:
As Daniel Alcanja put it in the original article, “It’s very important to watch how [a developer] codes, and how [a developer] is thinking about the problem.” The follow up conversation is where that happens.
Most teams get the best results combining a short simulation for screening with a live coding interview for the final round.
Glider AI Coding Simulations replicate a real working environment. In the WebIDE, candidates run complete projects, and the platform auto evaluates frontend, backend or full stack skills on the stack you choose. A virtual desktop option gives candidates a simulated Linux machine. Role based tasks cover data science, frontend, backend, QA and DevOps work, such as building a FIFO cache or implementing paginated REST endpoints.
For broader screening, Technical Assessments cover 250+ languages and technologies with auto scoring and shareable skill reports, and AI Proctoring helps deter plagiarism and proxy test takers. For role specific questions to pair with your tests, browse the Glider AI interview questions library.
Many coding tests measure memorized algorithms under artificial conditions instead of the work the role involves. When the task does not resemble the job, the score does not predict how the person will perform on it.
About 45 to 60 minutes is a good target for a screening test. Longer tests lower completion rates, especially among experienced engineers who have other options.
Decide your policy before you test and tell candidates. If engineers use AI assistants on the job, allowing them with tracking can produce a more realistic picture than a strict ban.
A coding test usually presents short, isolated problems. A coding simulation gives candidates a realistic project in a full environment, which shows how they structure, debug and deliver working code.
Use proctoring, plagiarism checks and unique question sets, and follow up with a live conversation about the submitted code. Candidates who did the work can explain it.
It is risky. Resumes and interviews are weak evidence of coding skill on their own. A short, realistic test gives hiring managers comparable evidence before they invest interview time.
If strong engineers keep failing your test, or weak ones keep passing, the test is the problem. Replace puzzles with realistic work using Glider AI Coding Simulations, and give your hiring managers evidence of how candidates actually build software.
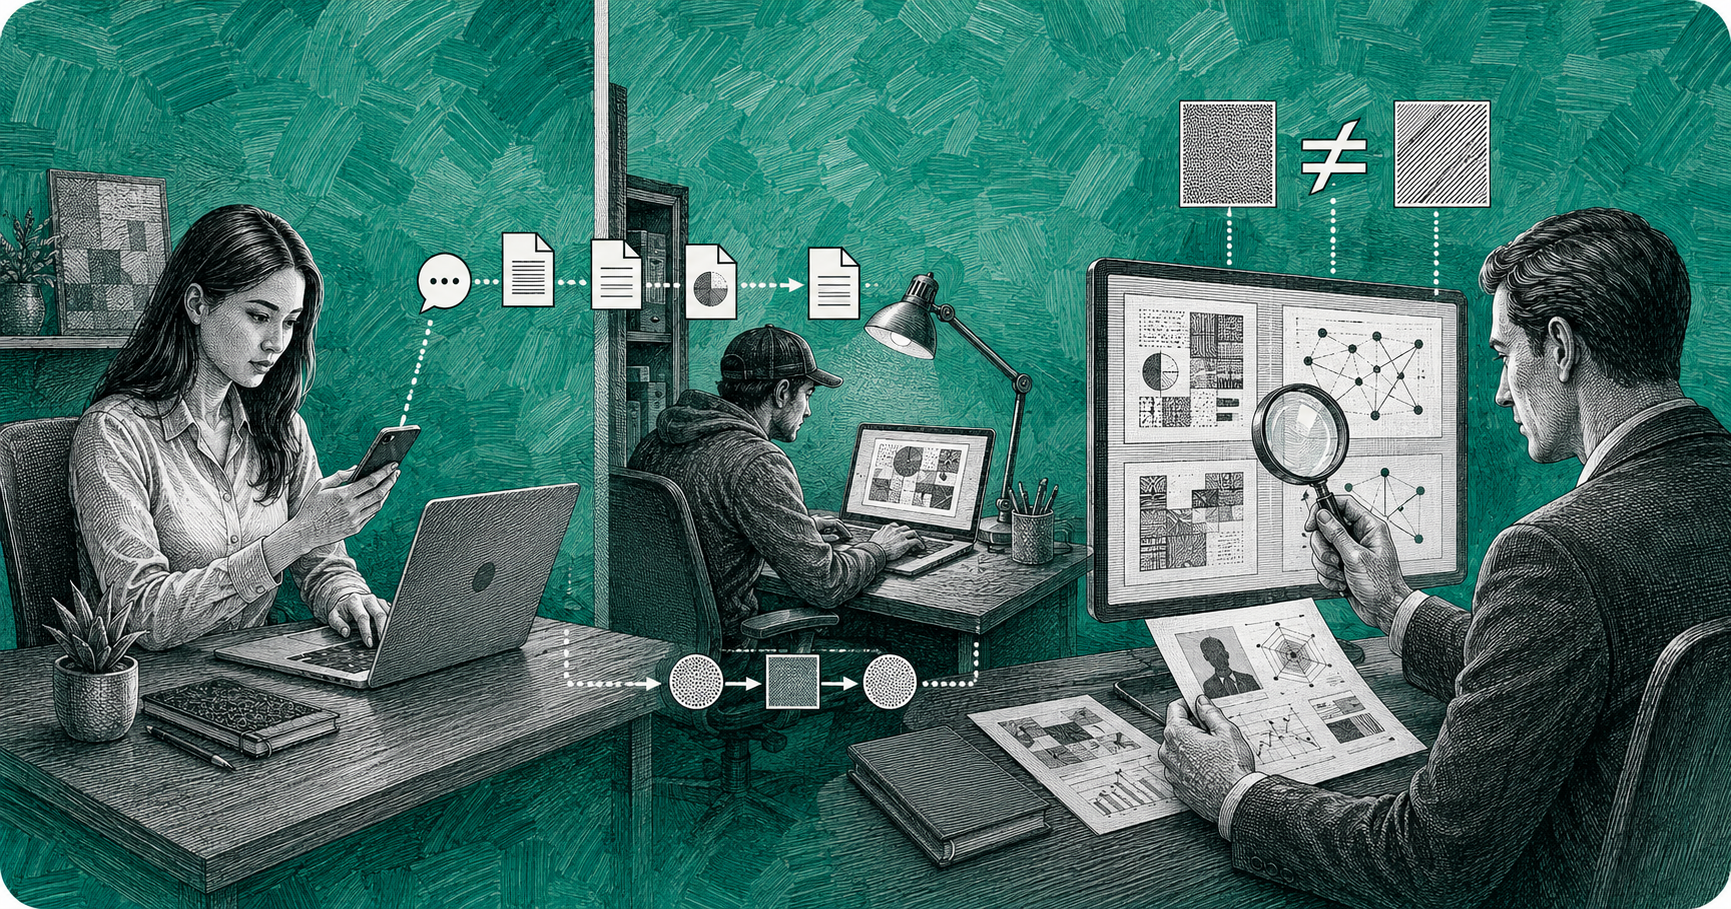
Take home assignment outsourcing happens when a candidate has someone else, a freelancer, a friend, or a paid ghost writing service, complete their take home coding, design, or writing test for them. Because the assignment is done alone, on the candidate’s own schedule, and away from any interviewer or proctor, nothing about the format itself […]
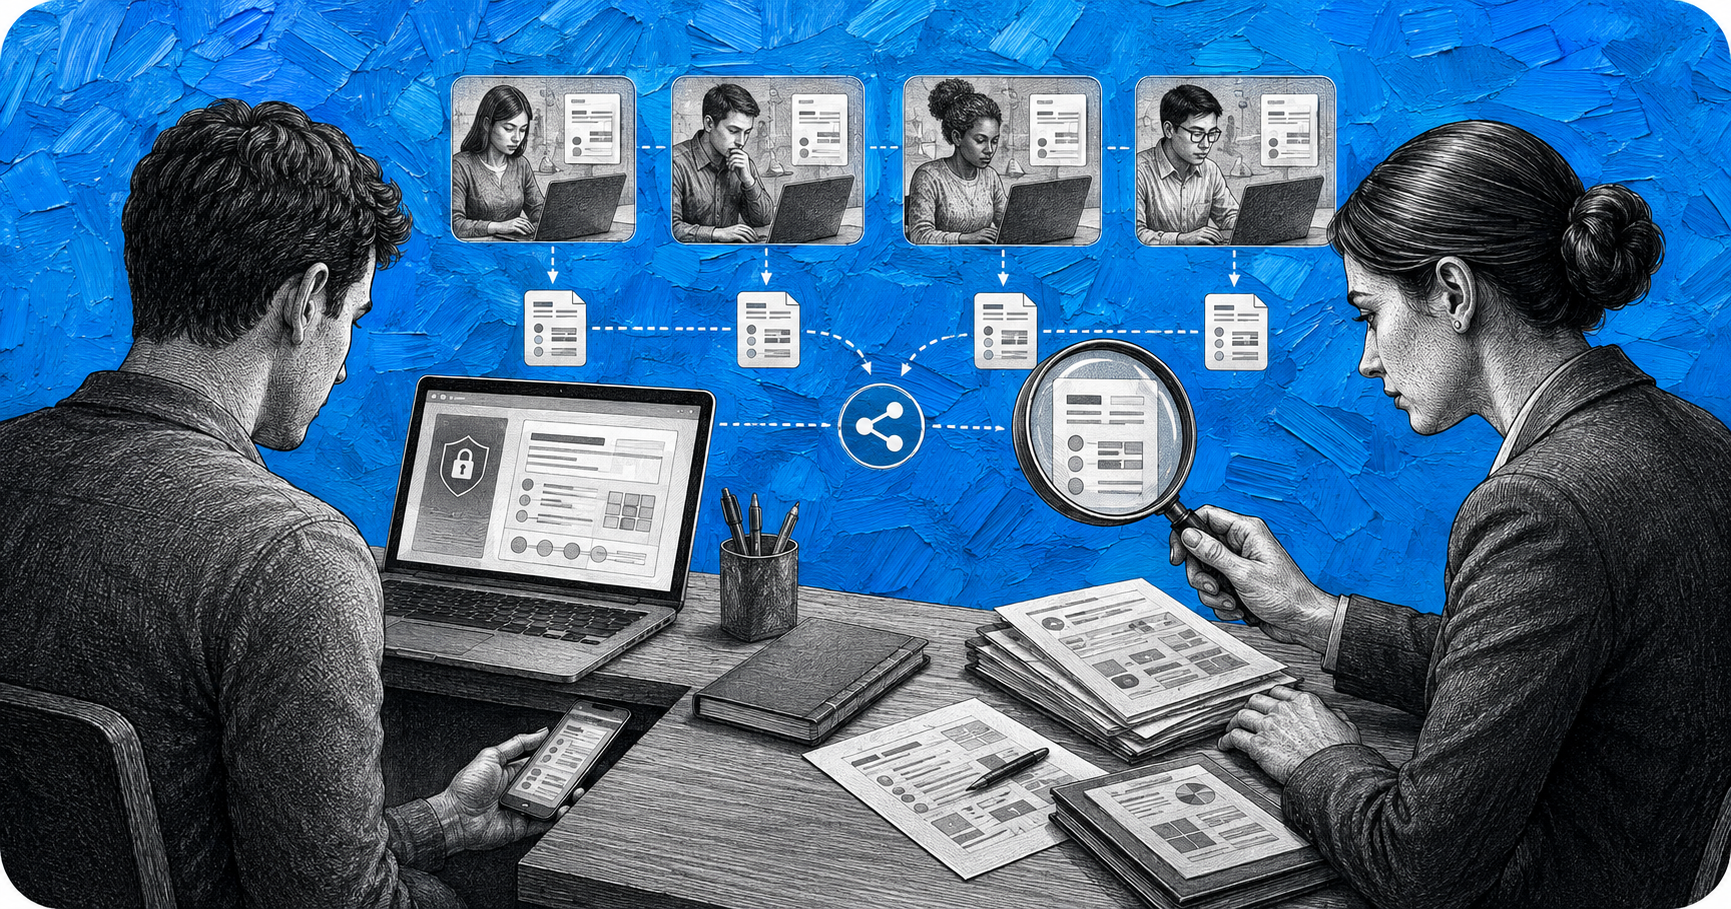
Leaked interview questions are exact, or nearly exact, copies of a company’s real assessment or interview questions that have been collected, compiled, and shared, often for a price, so that later candidates can memorize the answer before they ever see the question live. This is a test bank leak: a candidate is not solving a […]
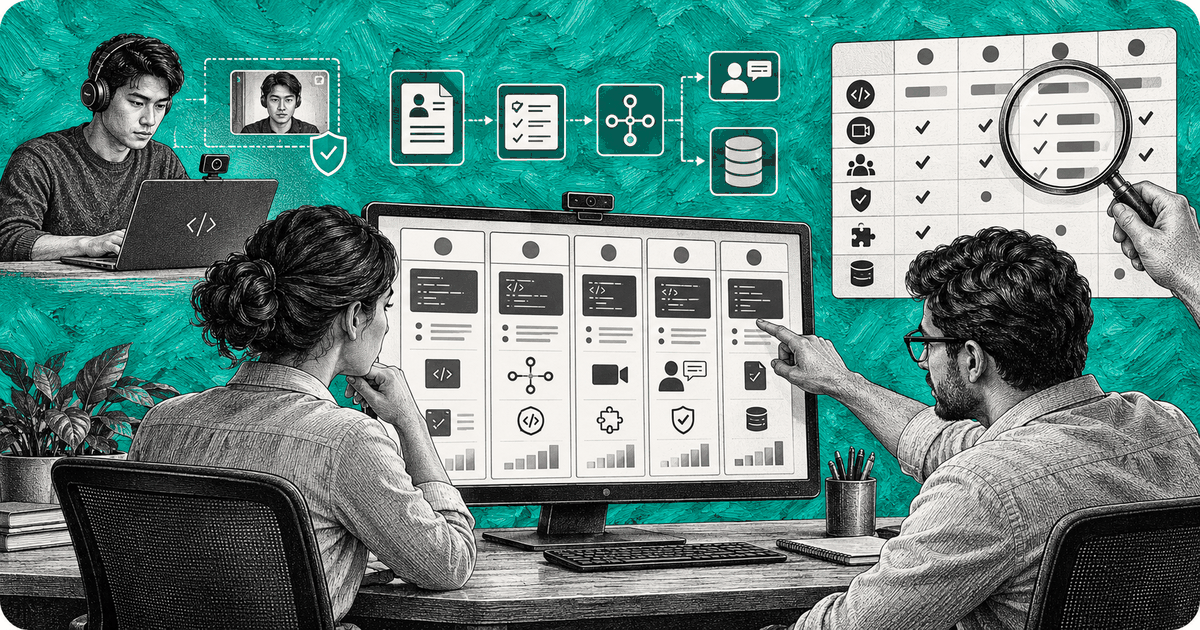
You posted one backend role and got 900 applicants. Some can code. Some can explain their code. A few used a proxy test taker last time they applied somewhere. The tool you choose for the first screen decides which of those people reach your hiring managers, so picking it is worth more than an afternoon […]

