

Make talent quality your leading analytic with skills-based hiring solution.
You can trust an AI recruiting tool when you can inspect three things: the data it held before it started, the method it followed while it worked, and the checks it ran before it handed you a result. Everything else in a vendor demo is decoration. This page gives you the three checks, the literal question to put to a vendor for each one, and what the evasion sounds like when it comes back.
Each check maps to a different failure. Bad input data produces a confident answer about the wrong thing. A bad method produces an answer nobody can repeat. Missing output checks mean nobody catches either before a candidate is rejected.
| Check | What it tests | The one question to ask |
|---|---|---|
| 1. Intelligence before it starts | Whether the tool knows the role and the market before it scores anyone | “Where does the data behind this score come from, and when was it last refreshed?” |
| 2. Method while it works | Whether the same input gives the same output, and whether the steps are visible | “Show me the steps the tool took to reach this specific conclusion.” |
| 3. Checks before anyone acts | Whether the output is verified, traceable and safe to act on | “What does this tool refuse to answer, and what happens to that case?” |
A recruiting tool is only as good as what it knows before the first candidate arrives. If it does not know what the role requires in your market, it ranks people against a generic template and sounds certain doing it.
The right intelligence is specific: labeled attributes rather than keyword matches, career progression data rather than one snapshot of a resume, and a refresh cadence you can name. Findem publishes 1B+ career paths mapped and 2M+ labeled Success Signals built with 200+ contributing experts, and 75 to 100 Success Signals per profile. Hold a vendor to figures like those during a trial.
“Where does the data behind this score come from, how much of it is labeled by people versus inferred by the model, and when was it last refreshed? Show me one profile and name the attributes the tool used.”
Then the question that breaks most calls: “if I hire for this role in a market you have less data on, how does the output change, and does the tool tell me?”
“We use a large language model trained on a massive dataset of hiring outcomes.” That names nothing: no source, no refresh date, no split between labeled and inferred. The same evasion in a politer suit is “our data is proprietary, so we can’t get into specifics.” A vendor can protect a method and still say what the inputs are and how current they are.
The most common version is a pivot to integrations. “We pull straight from your ATS, so it’s your data.” That answers where the resumes come from, not where the judgment comes from. Press again. On how scoring quality gets measured, see how accurate AI candidate scoring really is.
A method is trustworthy when the same input gives the same output and you can see the steps in between. Ask the vendor to walk you through one conclusion, on screen, on a real profile. Not a slide.
Three properties matter. Repeatable, so two identical inputs produce one answer. Inspectable, so every conclusion points back to the evidence behind it. Bounded, so the tool stays inside a defined scope instead of improvising past what it knows. An agent architecture with explicit tool calls and logged steps gives you all three almost for free. A prompt wrapped around a model gives you none, and the framework for judging any AI agent goes deeper on that split.
“Show me the steps the tool took to reach this conclusion, on this candidate, right now. If I run the same profile tomorrow, do I get the same score, and what would change it?”
“The model weighs hundreds of signals, so it’s not really possible to break down one score.” That is a statement about the vendor’s tooling, not the model. Plenty of scoring systems surface the top contributing attributes for a single decision. A vendor who has not built that view has never been asked for it.
Watch the demo that only shows finished output. If every screen is a ranked list and a score with nothing to click into, there is no method to inspect. Then there is the cooperative answer that delivers nothing: “sure, we have full explainability, it’s on the roadmap for Q1.” A purchase made in September cannot be defended in November with a feature shipping in January.
This is the check buyers skip, and the one that shows up later in a complaint. Ask what the tool verifies about its own output before a recruiter sees it, and what it does with the cases it cannot handle.
Four things belong here. A log an auditor can read. Evidence attached to conclusions rather than confidence alone. Abstention on cases outside the tool’s competence, routed to a person. A record of who saw what, when. Abstention is the most diagnostic: a tool that always answers is a tool that guesses when it does not know, and from the outside guessing looks identical to knowing. For that failure mode in practice, read what happens when an AI recruiting agent gets it wrong.
“What does this tool refuse to answer, and what happens to that case? Show me an audit log entry exactly as an auditor would see it, not as it appears in the demo view.”
“It always returns a recommendation, and the recruiter makes the call.” Read that closely. The tool has no abstention path, and the reviewer gets guesses styled exactly like findings. A related evasion: “we have a full audit trail,” followed by a screen showing a timestamp and a user name and nothing about what the tool concluded or why. Also reject the answer that offloads the check onto you: “you can configure your own review rules.” You probably can, and you should, but a vendor whose only safety story is your configuration has not built one.
Use this in the call. The strong answer column is what you are listening for. The weak answer column is what usually comes back first.
| Check | The question | A strong answer | A weak answer | Risk if you skip it |
|---|---|---|---|---|
| Intelligence | Where does the data come from, how much is human labeled, when was it refreshed? | Names sources, separates labeled from inferred, gives a refresh cadence, shows the attributes on one profile | “Trained on a massive proprietary dataset,” with no source, date or labeling split | The tool ranks candidates against a generic template and sounds certain about it |
| Method | Show me the steps behind this one conclusion. Is it repeatable? | Clicks into a single score, shows contributing evidence, states what would change it | “Hundreds of signals, can’t break down one score,” or explainability on a roadmap | Results you cannot reproduce or explain, and a rejection you cannot account for |
| Output checks | What does it refuse to answer, and what does an auditor see? | Shows an abstention path, a routed case, and a log entry with reasoning, not just access | “It always returns a recommendation,” plus a log view that only shows timestamps | Guesses reach recruiters styled as findings, and nothing survives a challenge |
Run the checks yourself inside the trial or the demo. Six tests cover most of it.
Run tests 1 and 2 in front of the vendor. Run 4 and 5 alone, afterwards, when nobody is narrating.
Score each check from 0 to 3 and add them up. Nine points possible, and the shape of the score matters more than the total.
Two rules make the score useful. Any zero is a stop, whatever the total says, because one unanswerable check is enough to make a rejection indefensible later. A total under 6 means you are buying on trust rather than evidence, which a team can choose deliberately but should not do by accident.
These bands are a practical starting point, not a researched standard. No published benchmark says 6 of 9 is the right threshold here. Adapt the cut line to your exposure: a team hiring 40 people a year in one state and a team running high volume hiring across eight jurisdictions should not share a threshold.
A person does. A tool that passes all three has earned the right to put a recommendation in front of a recruiter with its evidence attached, nothing more. The recruiter accepts it, overrides it, or sends it back.
Write that boundary into the contract, not just the internal policy. Findem does not make employment decisions: agent output is a recommendation a human reviews, and the platform carries a Trust Layer and an Agent Orchestrations Layer so the recommendation arrives with its reasoning attached. The Agentic AI Recruiter and the named agents, including the Calibration Agent, Screening Agent, Scheduling Agent and ID Verify Agent, work that way, with the Screening Agent and Scheduling Agent published under Glider AI branding.
Because a long checklist gets scored by whoever already wants the purchase. Thirty items give a sponsor thirty places to award partial credit, and 24 out of 30 reads like a pass even when the three that mattered were among the six misses.
The published alternatives share that shape. Cangrade, The Hire Hub, CVViz, BestHire, Hyring, ZYTHR and BizWorkHQ all publish evaluation checklists running from roughly a dozen items to several dozen, across features, security posture, pricing, integrations and bias language. Useful reference material, nearly impossible to carry into a meeting. Three checks survive the meeting: you hold them in your head, ask them in any order, and notice at once when one has gone unanswered. For the wider procurement view across commercials, security review and implementation, the checklist for buying AI hiring tech covers that ground, and what AI agents actually do in recruiting covers what you are buying in the first place.
The three checks also split cleanly by owner. Data is a vendor question, method is an architecture question, and output verification is a policy question your team answers whatever you buy.
This page is about evaluating a tool before you trust it. Two adjacent questions have their own pages.
It does not cover defending a decision after the fact. Once the tool is in place and a candidate has been rejected with its help, the question shifts from “is this vendor credible” to “can we show a reviewer how this decision was made.” Bias audits, candidate notice, documentation and sign off live on what it takes to stand behind an AI assisted hiring decision.
It also does not cover whether to buy at all. For an internal build weighed against a vendor, see building versus buying AI recruiting tools, and for whether running one of these tools needs a data team, whether you need a data team to run an AI recruiting agent answers that directly.
Ask where the data behind the score comes from, how much is labeled by people rather than inferred, and when it was last refreshed. Every other answer in the call depends on it. A vendor who cannot name a source or a refresh cadence is asking you to trust an output without an input.
The answer changes register. A specific question about data or method comes back as scale (“massive dataset”), secrecy (“proprietary”), or a pivot to integrations. The tell is that you could not repeat the answer to a colleague as a fact. Ask again in different words and see whether it holds still.
Checks 1 and 2 work in a demo, since both are a question plus a click into one real profile. Check 3 needs a trial, because you need a log export and the cases the tool declined during a real run. Ask for a trial on your own requisitions, not a sandbox with sample data.
Turn the three checks into three required written answers: data provenance with refresh cadence, how one conclusion traces to its evidence, and the abstention and logging policy including what an auditor sees. Require an artifact per answer, then add your standard security, retention and integration sections.
Four functions at least: talent acquisition, legal or compliance, someone technical who can read an audit log, and the hiring manager who acts on the output. The compliance seat matters most in jurisdictions with notice or audit requirements, since that person gets asked for records later.
No. SOC 2 covers controls over security, availability and confidentiality. It says nothing about whether a candidate score is accurate, repeatable or explainable. Ask for it, keep it on file, then run the three checks separately.
It proves a defined test ran on a defined dataset at a defined time, and it is only as informative as those definitions. Ask which selection rates were compared, which population the data came from, and who ran it. A summary that reports a conclusion without the method is marketing with a statistic in it.
Long enough to run a trial on live requisitions, which means weeks rather than days, because checks 2 and 3 need real output to inspect. The trial is always what gets compressed, and the trial is where the three checks actually get answered. A call ending in a verbal yes on all three has told you about the rep.
No, for a practical reason. An unexplained score cannot be reproduced, corrected or defended, so the first time a reviewer or a candidate challenges one you have nothing to show. Accuracy and transparency are separate properties, and how accurate AI candidate scoring really is covers how the first one gets measured.
Fair about the model, and it does not excuse the rest. A vendor can decline to describe their architecture and still tell you what data goes in, how fresh it is, what evidence supports one output, what the tool abstains from, and what lands in the log. If “proprietary” answers all five, the word is doing work it should not do.
No. You do not need a data team, data scientists, or engineers to run an AI recruiting agent, as long as the agent you are being offered is the kind that matches the technical capacity you actually have. What decides the answer is not the size of your team, it is which of three setup […]
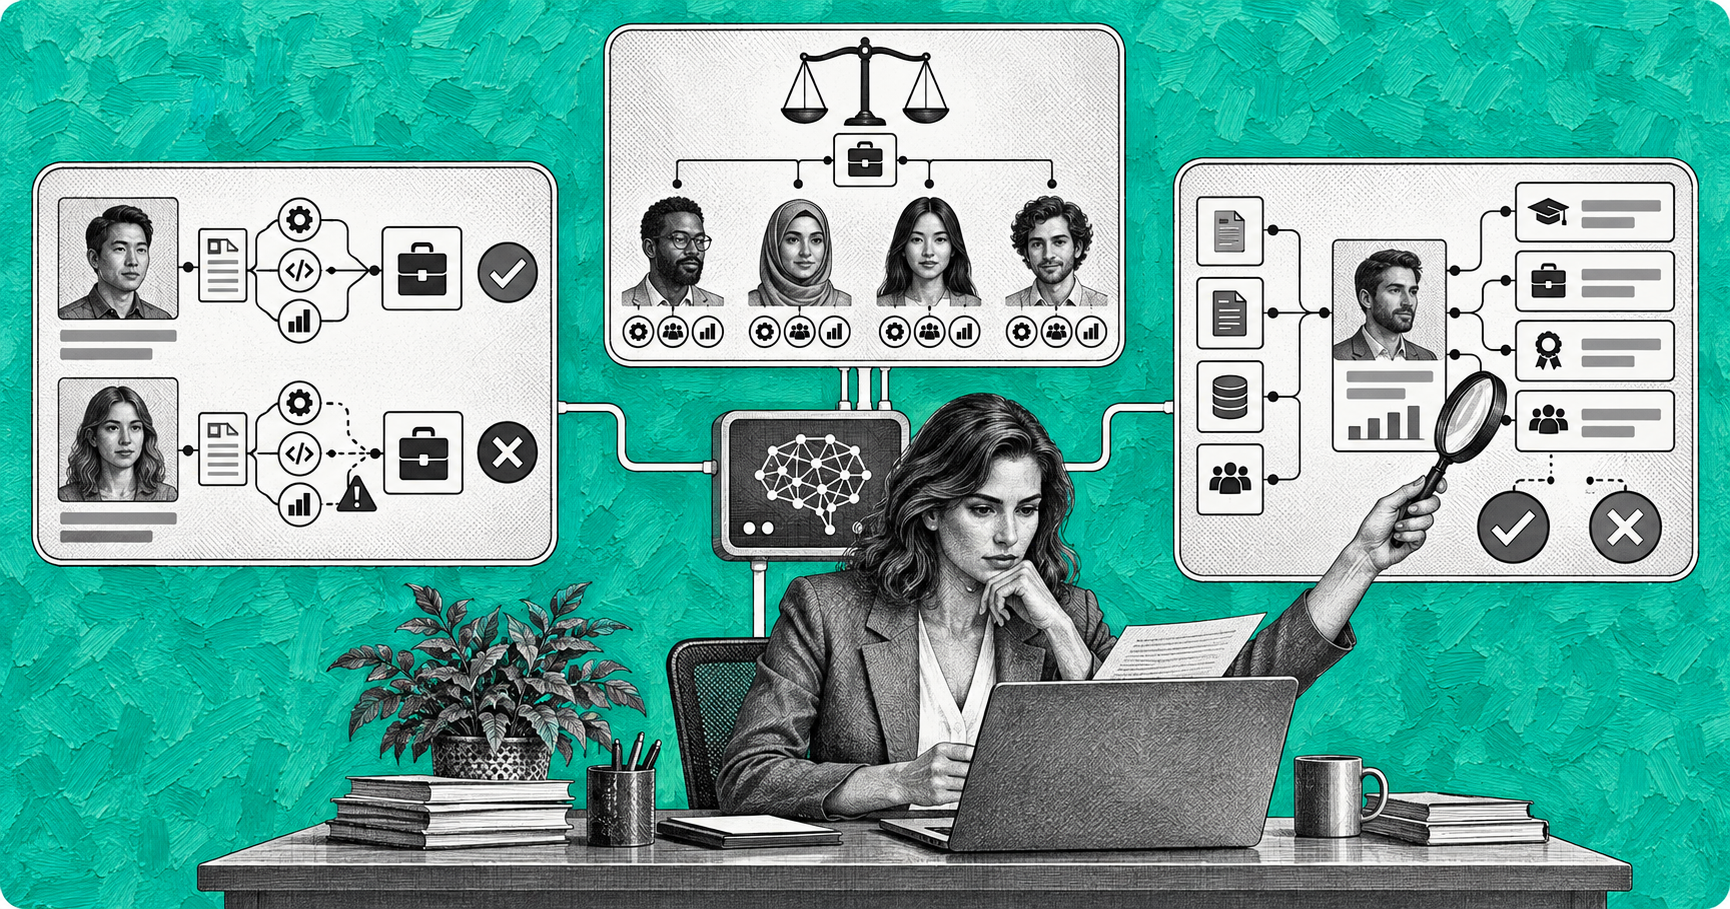
An AI agent that hands you a confident wrong answer is more dangerous than one that hands you nothing, because confidence is what gets acted on. The framework below is three questions you can ask of any agentic tool before you trust its output: what data did it reason over, whose method did it follow, […]
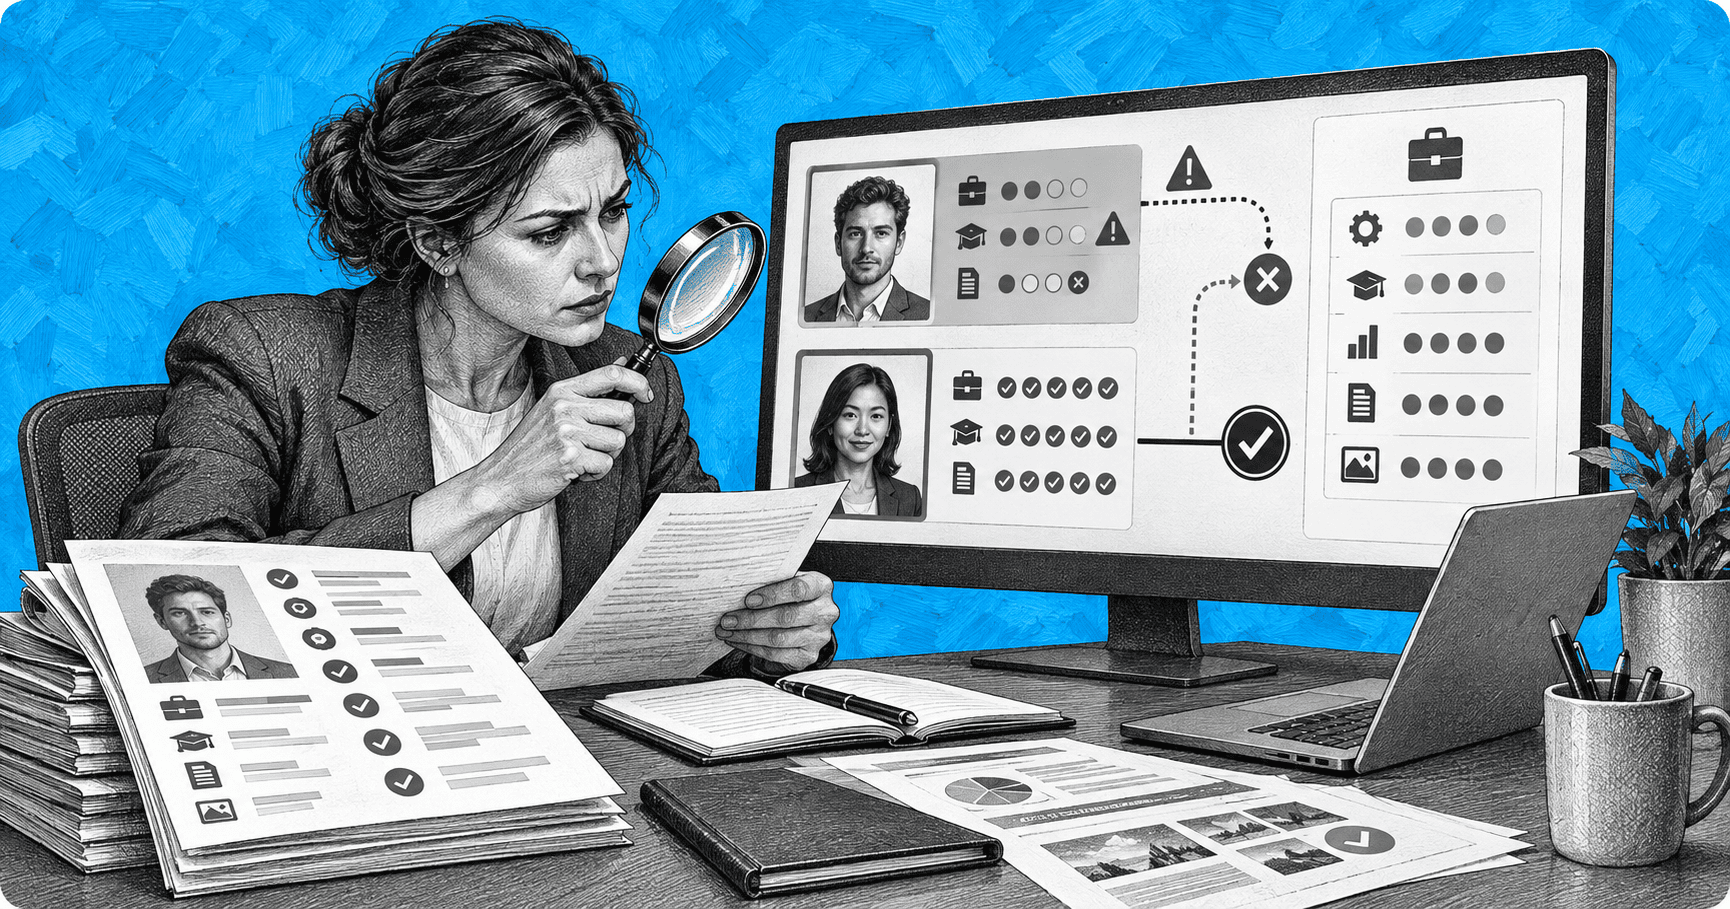
Yes, AI recruiting agents get things wrong, and the useful question is not whether it will happen but whether your process is built to catch it, explain it and let a person fix it before it reaches a real candidate or a real client. An agent can misread a work history, infer a skill nobody […]
