
Make talent quality your leading analytic with skills-based hiring solution.
To hire a big data engineer, define the data platform and scale the role supports, test hands on skills in Spark, SQL, Python or Scala and streaming tools, and use a realistic pipeline task instead of resume filters. Then run a structured interview on design, reliability and cost tradeoffs before making an offer.
Big data engineers build the pipelines everything else depends on. When one fails, dashboards go stale, models train on bad data and finance asks why last month’s numbers changed. That’s why the hire is hard to get wrong and easy to get slow. Resumes list the same tools (Spark, Hadoop, Kafka, Airflow), so recruiters can’t tell from keywords who has run production workloads. Glider AI Technical Assessments let teams test those tools directly so the shortlist reflects real ability.
Agree with the hiring manager on four things:
This is the difference between a data engineer who maintains nightly ETL jobs and one who designs a streaming platform. Use the big data engineer job description as a starting template and adjust it to your stack.
| Skill area | What strong candidates show | How to test it |
|---|---|---|
| Distributed processing | Spark jobs that partition, cache and join efficiently | Spark task with a performance constraint |
| SQL | Window functions, complex joins, query tuning | SQL questions on realistic schemas |
| Programming | Clean, tested Python, Scala or Java | Coding task with unit tests |
| Streaming | Kafka topics, consumer groups, exactly once tradeoffs | Scenario questions and a design discussion |
| Orchestration | Airflow or similar DAG design, retries, backfills | Debugging a failing pipeline |
| Data modeling | Schemas that serve analytics and change safely | Design exercise |
| Cloud and cost | Storage formats, cluster sizing, cost awareness | Scenario questions |
Good big data engineers don’t always carry that title. Look at backend engineers who own data heavy services, analytics engineers who have moved into pipeline work, and data platform engineers in adjacent industries. A skills first screen makes these candidates visible because it judges what they can do rather than what their last title was.
Put the assessment before the first technical interview. It saves engineering time and gives every candidate the same starting point.
A practical big data engineer assessment includes:
Sample Spark SQL question: given an events table with user_id, event_type and event_time, return each user’s first purchase event and the number of sessions before it. Look for correct window functions, null handling and an explanation of how the query scales.
Glider AI supports hands on environments including Jupyter Notebooks and SQL for data work, plus coding simulations for full project tasks. Proctoring and identity checks confirm the candidate who scored well is the one you interview.
Use the assessment results to choose where to dig in. Strong question areas:
The big data engineer interview questions post has a longer question bank by topic.
Score each candidate on the same skill areas used in the assessment and interview. A scorecard keeps the final debate on evidence and stops one strong opinion from deciding the hire.
For more on the friction technical recruiters face, see challenges recruiters face in technical hiring.
A big data engineer needs distributed processing with Spark or similar tools, strong SQL, programming in Python, Scala or Java, streaming with Kafka, pipeline orchestration, data modeling and an understanding of cloud storage and cost.
Use a hands on assessment with a Spark or PySpark task, SQL questions on realistic schemas and a scenario on data quality issues such as late or duplicate events. Follow up with a design discussion in the interview.
A big data engineer is a data engineer who specializes in distributed systems built for very large or fast moving datasets, typically using Spark, Hadoop, Kafka or a lakehouse. Many companies now use the titles interchangeably.
It varies with the market and the role’s seniority, but long delays usually come from manual screening and too many interview rounds. A skills assessment up front and a single structured technical interview shorten the process without lowering the bar.
Yes. The job is building pipelines, so the assessment should include real code in Spark, SQL and Python or Scala. Avoid generic algorithm puzzles that don’t reflect data work.
Platform design, streaming versus batch tradeoffs, schema evolution, pipeline testing, reliability and cost control, plus how they have mentored others and influenced technical direction.
Every big data resume lists the same tools. The difference shows up when a candidate has to build something. Use Glider AI Technical Assessments to test Spark, SQL, streaming and pipeline design before the interview, so your data team spends time only with engineers who can do the work.
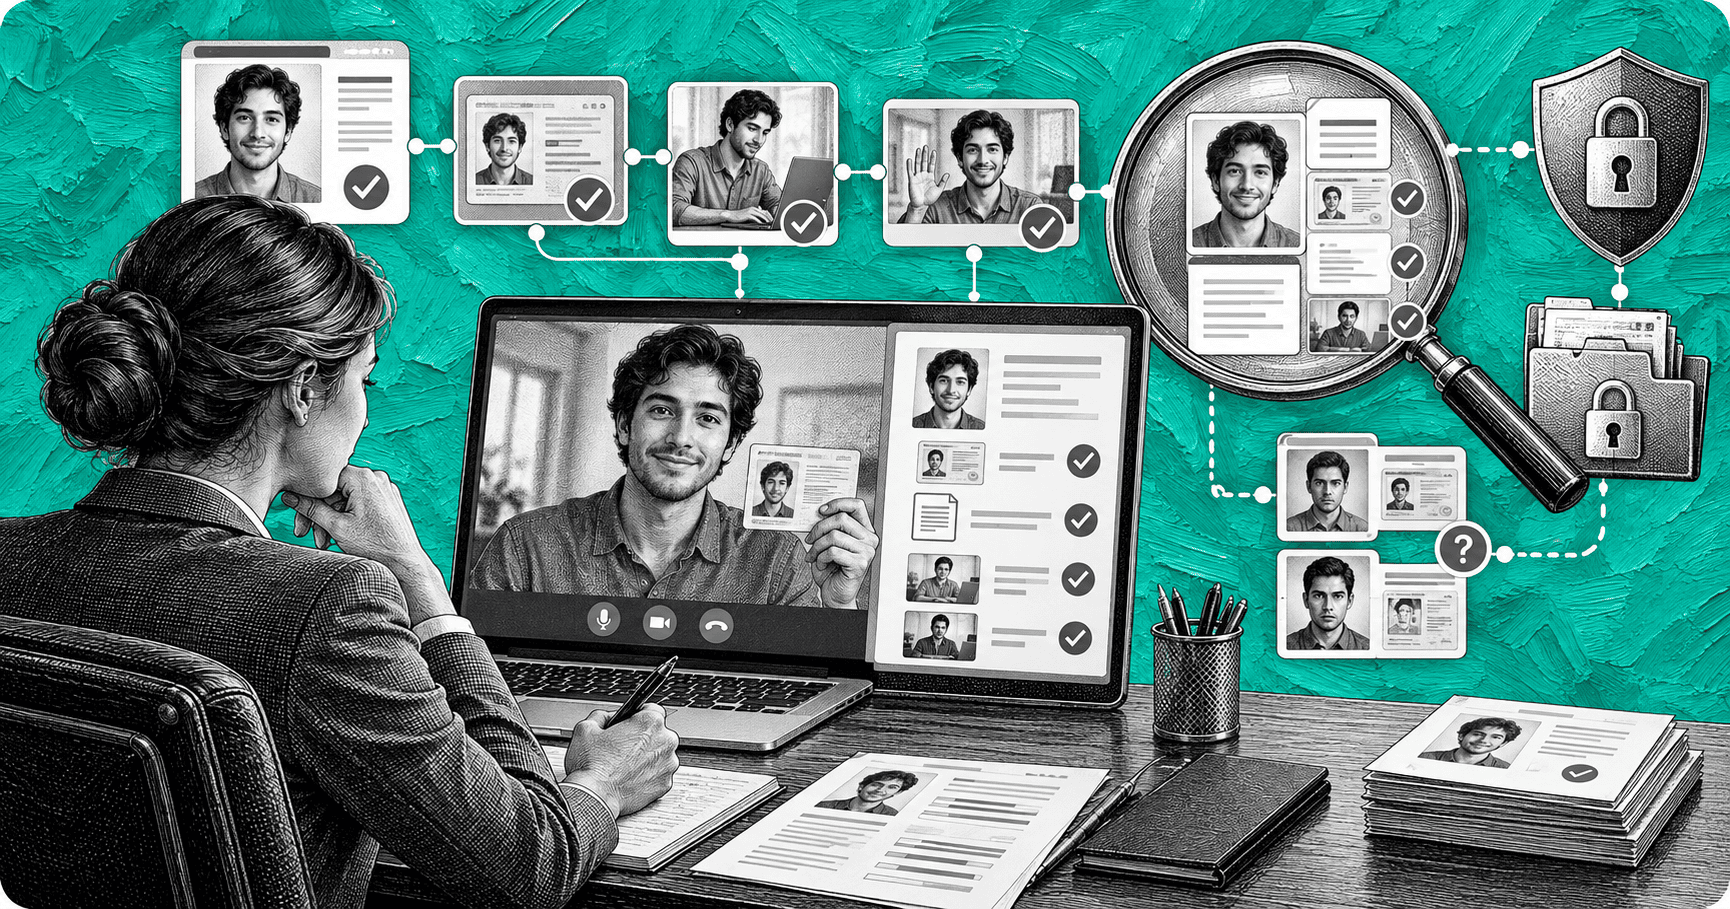
A recruiter screens a strong candidate on video, a hiring manager runs a solid technical round, and an offer goes out. On day one, the person who logs in is not the person who interviewed. Nobody on the team did anything careless. The process simply never confirmed who the candidate was. That gap is why […]
Introduction Technical roles are some of the hardest to fill. The process is a landmine of recruitment challenges. HR teams often find themselves under-resourced and struggling to find suitable talent, while engineers waste too much time interviewing candidates who don’t meet the necessary qualifications. Meanwhile, high-quality candidates get frustrated by slow and inefficient hiring processes and […]
What is QA and Testing? Quality Assurance (QA) and testing are integral processes in software development aimed at ensuring the reliability, functionality, and usability of applications. QA involves establishing standards and procedures to monitor and improve the software development lifecycle, focusing on preventing defects and identifying areas for optimization. It encompasses various activities such as […]
